🏗️ Documentation as Infrastructure
Explain How we used to study and learn
seminars, you went there to tutorials, lectures, your friends house to study whiteboards
Then give quora, stackexchange examples
give the example of chegg and how it crashed when people could get it for free
Now, AI tutors are the future of learning people knowledge
What is valuable is the human connection, sharing it with others.
people don't go to websites anymore only stay in their ai interface
phone companies now rolling out AI native operating systems and give examples
Different ways of accessing this content. If you actually want to study it and understand or if you just want to get something fixed quick.
Grokipedia is another example of AI generated content from the web.
Very soon, if not already the case, content written by AI frontier models will be more reliable than any human. We are getting to the point where it is like having a 5th grader (human) review the work of a college professor (ai).
With the advent of AI and especially LLM's it has become clear that education and the way we absorb information will never be the same again. Not that education has not changed overtime, but all content before LLM's and AI was written and curated by humans regardless if it was digital or not. With
It is crucial that all AI generated content is fact checked manually by humans. That is what we try to do here as well. If you add content no matter AI generated or not it will be fact checked by the community to make sure that hallucinations do not enter the documentation pages.
The way we absorb information and the way we educate people has always changed over time, but something drastically changed since the advent
Richard Feynman and Ablert Einstein clearly understood that you only understand something if you can eplain it to a 14 year old.
Well LLM's and AI agents could obviously behave both ways, they could teach but they could also pretend to be 14 year old.
Hence, the LLM can also actually test on different levels if you understand the content or not.
However, what is important in all of this is the trainings data! if the trainings data is incorrect then also teaching will be incorrect.
ChatGPT, Claude, AI overview
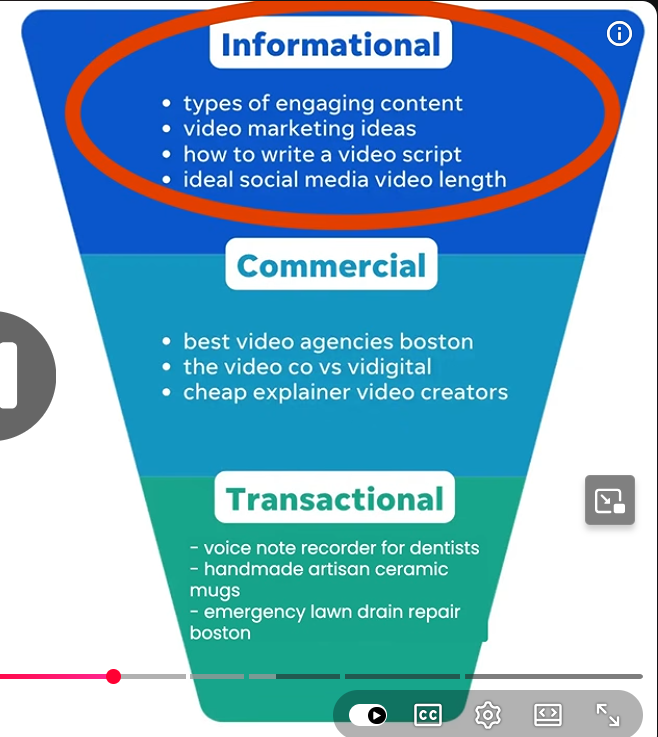
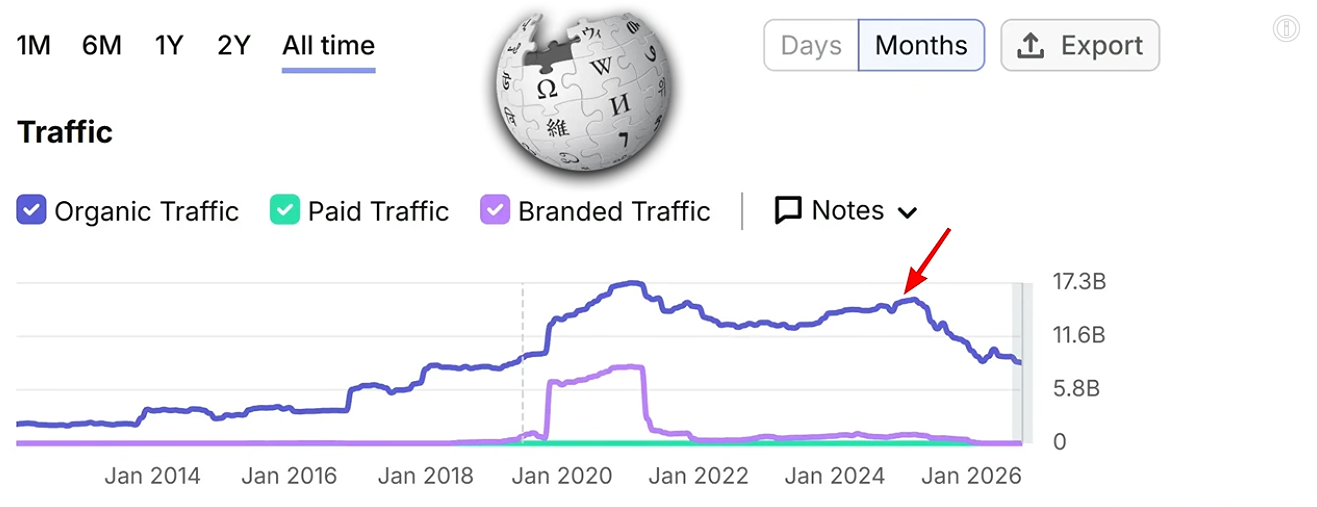
go to the actual forums, websites, documentation pages than ever before. The reason is quite simple and it is called drum roll 🥁, surprise surprise Large Language Models and AI Agents 🤖. These systems have been trained on the whole internet including all the tutorial websites or any website you always used in the past.
Before, this boom most people would go to the knowledge forums like Quora, Stack exchange, Reddit, Documentation pages and Blogs about basically anything. Yes, people also copied other websites and then made sure to end up on the top of search engine to earn money through ads ;). But for most of it, humans would visit websites for information, knowledge and studying.
Today, that turned on its head and most people are almost never leaving their LLM/AI agent user interface unless they are actually studying a subject or want to build something that takes a bit more effort than just clicking through some settings of a well known device or app.
So all these documentation instances are really for people that are interested in the subject. It won't be for people that just want their home server up and running and install apps.
For the ecosystem, the implications are murkier. LLMs were trained on Stack Overflow's corpus. If the site continues declining, where will future training data come from? Who will catch and correct the errors that LLMs confidently present?
The question isn't whether AI will displace these platforms. The question is what comes next - how we'll generate, verify, and maintain the knowledge that future AI systems will need to stay accurate.